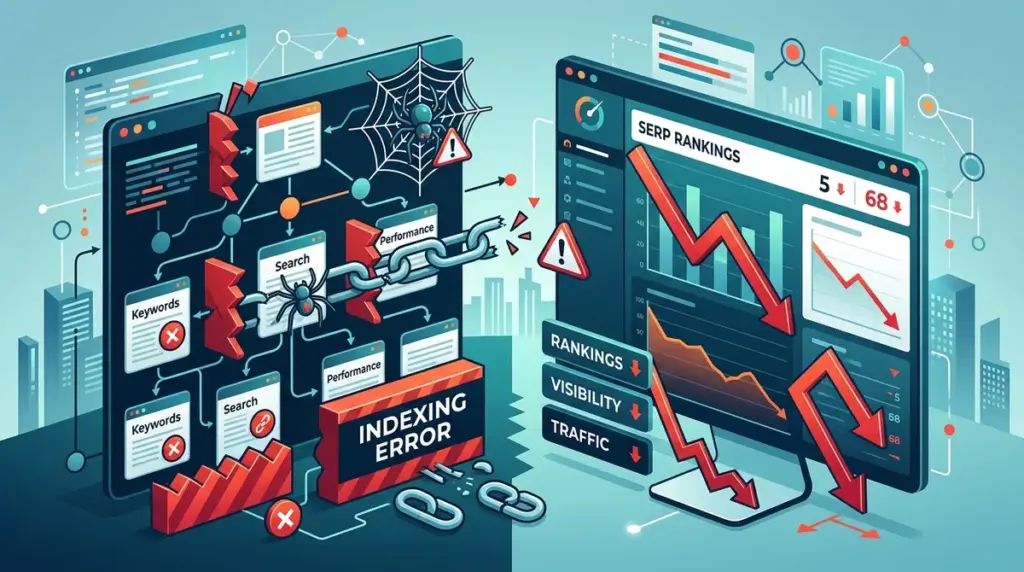
Search engines cannot rank what they cannot process. While content quality and backlink profiles dominate the conversation around SEO, they are functionally irrelevant if the technical pipeline—crawling and indexing—is broken. For an SEO professional or site owner, a single misconfiguration in a robots.txt file or a poorly managed canonical tag can negate months of content production. Understanding the mechanics of how bots navigate your site is the difference between a high-performing asset and a "ghost" page that exists on your server but never reaches the SERPs.
The Mechanics of Crawl Budget and Resource Allocation
Googlebot and other search crawlers do not have infinite time or processing power for a single domain. "Crawl budget" is the combination of crawl rate limits (how much the server can handle without slowing down) and crawl demand (how much Google actually wants to crawl the site). If your site structure is inefficient, the bot may exhaust its budget on low-value pages—such as faceted navigation filters, old session IDs, or duplicate staging URLs—before it ever reaches your high-converting money pages.
When crawl budget is wasted, new content takes longer to appear in search results, and updates to existing pages aren't reflected in the index for weeks. This latency directly impacts your ability to react to market trends or fix ranking drops. High-authority sites with millions of pages feel this most acutely, but even smaller sites suffer if their server response times are sluggish, as slow responses trigger the bot to scale back its activity to avoid crashing the site.
Technical Blockers: Robots.txt and HTTP Status Codes
The robots.txt file is your first line of defense, but it is frequently the source of self-inflicted wounds. A common error is Disallowing a directory that contains the CSS or JavaScript files necessary to render the page. If the bot cannot "see" the layout because the styling is blocked, it may categorize the page as mobile-unfriendly or low-quality, suppressing its rank.
Status codes play an equally vital role. A 404 (Not Found) error is a dead end that wastes crawl energy. However, a 5xx (Server Error) is more dangerous; it signals to the search engine that your infrastructure is unstable. If a bot encounters frequent 5xx errors, it will intentionally reduce its crawl frequency to protect your server, leading to a rapid de-indexing of previously stable pages.
The Gap Between Crawling and Indexing
It is a common misconception that crawling automatically leads to indexing. Indexing is a selective process where the search engine evaluates whether a page is worth the storage cost in its database. If a page is crawled but not indexed, it often stems from a "quality threshold" issue or a technical directive like the noindex tag.
Common reasons for crawl-but-no-index status:
- Thin Content: Pages with minimal unique text that offer no distinct value over existing indexed pages.
- Duplicate Content: Multiple URLs serving the same content without proper canonicalization.
- Rendering Failures: Heavy reliance on client-side JavaScript that fails to load content within the bot's timeout window.
- Redirect Chains: Excessive hops (A to B to C to D) that cause the bot to abandon the path before reaching the final destination.
Warning: Never use a
noindextag on a page you are also trying to consolidate via arel="canonical". Thenoindexis a powerful directive that can override the canonical hint, potentially dropping the entire group of pages from the index entirely.
Canonicalization and the "Winner" Page
When you have multiple versions of a page (e.g., tracking parameters, different sorting orders, or HTTP vs. HTTPS), Google must choose a "canonical" version. If your internal linking points to one version while your canonical tag points to another, you create a conflict. This ambiguity forces the search engine to guess which page should rank. Often, it chooses the wrong one, or worse, splits the "ranking signals" across multiple URLs, ensuring none of them reach the first page.
JavaScript Rendering and the Two-Pass Indexing Problem
Modern web frameworks like React, Angular, and Vue rely heavily on JavaScript. Google uses a "two-pass" system for these sites. First, it crawls the HTML; later, when resources become available, it renders the JavaScript to see the full content. This delay can range from a few hours to several days. If your primary keywords and links are injected via JavaScript, your site may experience "partial indexing," where the page is in the index but doesn't rank for its core terms because the bot hasn't processed the rendered layer yet. For commercial sites, this delay represents lost revenue during product launches or seasonal sales.
Auditing Your Site for Indexation Parity
To ensure your rankings accurately reflect your content's value, you must align your "crawled" data with your "indexed" data. This requires a systematic audit of your sitemaps and Search Console data. If your XML sitemap contains 1,000 URLs but only 600 are indexed, you have a 40% "indexation gap." This gap usually points to a cluster of technical debt or low-quality content that is dragging down the perceived authority of the entire domain.
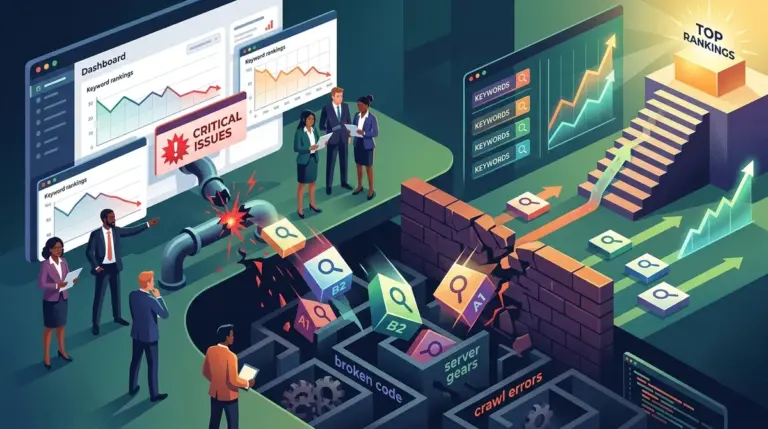
Check for "Crawl Errors" in your logs. If you see a high volume of 404s for pages that should be live, your internal linking is pointing to ghosts. If you see 301 redirects that lead to 404s, you are leaking link equity. Every broken link is a leak in your SEO "bucket" that prevents your rankings from reaching their full potential.
Establishing a Technical Monitoring Workflow
Technical SEO is not a one-time setup; it is a maintenance requirement. As sites grow, plugins are added, and CMS updates occur, new crawl blocks can emerge. A robust monitoring workflow should include weekly checks of the "Index Coverage" report to identify new exclusions. Pay close attention to the "Crawled - currently not indexed" category, as this is the primary indicator that Google finds your content but deems it unworthy of the index. Addressing these issues—by either improving the content or consolidating it with other pages—is often the fastest way to see a sitewide lift in rankings without building a single new backlink.
Frequently Asked Questions
How long does it take for Google to fix an indexing issue?
Once you have resolved the technical blocker (e.g., removed a noindex tag or fixed a 404), it typically takes between a few days and two weeks for Google to recrawl and update the index. You can accelerate this by using the "Request Indexing" tool in Search Console for individual pages.
Can a site rank if it has crawl errors?
Yes, a site can still rank, but its performance will be inconsistent. Crawl errors act as "noise" that prevents search engines from fully understanding your site's structure. Over time, high error rates lead to a loss of trust, which can result in lower rankings for even your healthy pages.
What is the difference between a crawl block and an index block?
A crawl block (via robots.txt) prevents the bot from even looking at the page. An index block (via noindex meta tag) allows the bot to see the page but instructs it not to store it in the search results. You should never use robots.txt to try and remove a page from the index; use a noindex tag instead.